
Discus Fish of Cobo and Samuel Tse of Animoca Brands discuss how AI agents, digital identity and blockchain could change the way money moves.
Updated
November 2, 2026 12:03 PM
The Agentic Economy Summit at CVCF 2026 explores how AI agents and digital assets could shape the future of business and finance. IMAGE: CYBERPORT
For an AI agent to manage money on someone’s behalf, it needs more than the ability to follow instructions. It must be able to establish whom it represents, access funds and transact within agreed limits.
These are among the questions informing the discussion of AI and digital assets at Cyberport Venture Capital Forum (CVCF) 2026. Ahead of the forum, Discus Fish, CEO and Co-founder of Cobo, and Samuel Tse, Head of Investment and Corporate Finance at Animoca Brands, shared their views on how this convergence could develop—and where they see opportunities for businesses.
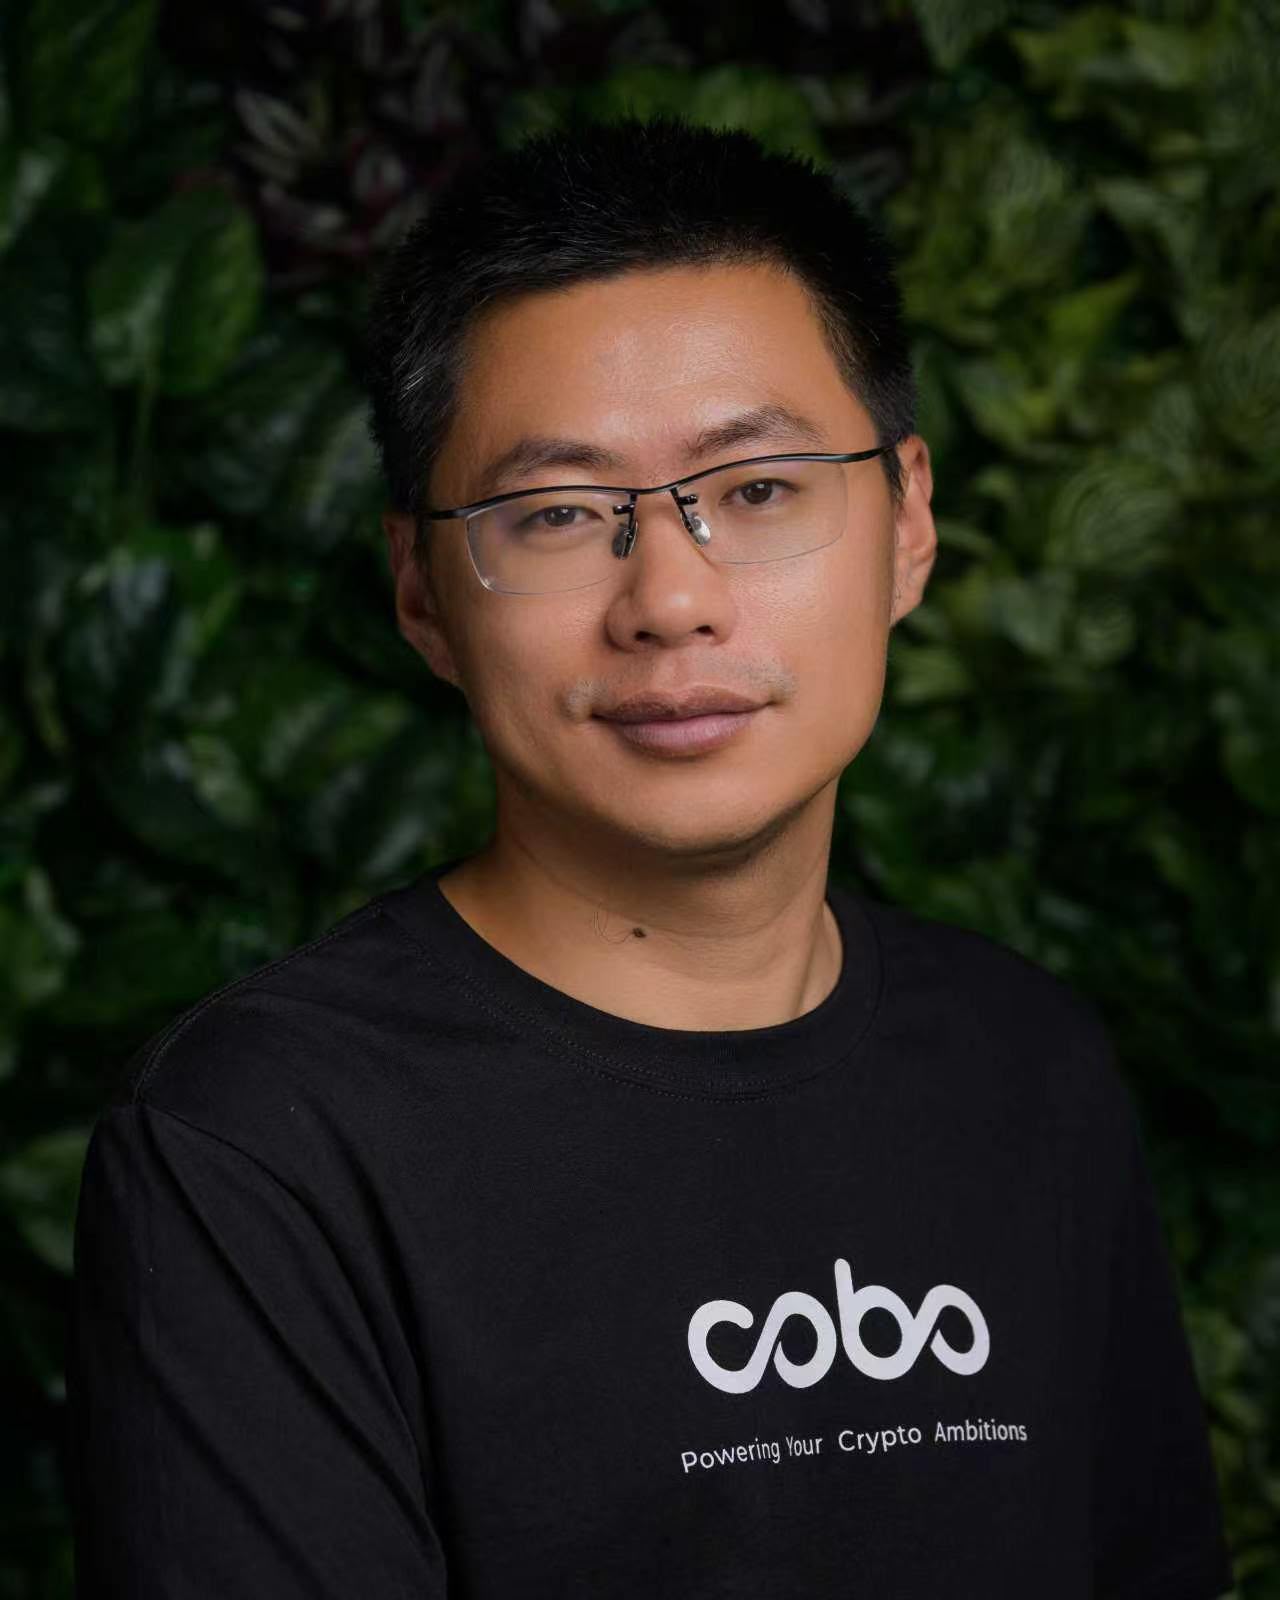
Discus Fish points to a longstanding challenge: blockchain can be difficult for everyday users to navigate, but AI agents may find it easier to interact with these networks.
“Blockchains have always been hard for ordinary people to use. AI agents may be better users: the chain is fully transparent and every record is traceable, which suits agents well.”
His outlook comes with a qualification. Both the agents and the networks they would use still need to develop.
“Agents aren’t capable enough yet, and chains are still adapting. But once agents truly run on-chain, the number of users and what’s possible will grow by an order of magnitude.”
Discus Fish says blockchain could reshape how financial assets are issued, traded and settled over the next five years. He also notes that institutional adoption has progressed faster than Cobo initially expected, with individual users no longer leading the shift. “Since 2017, we have believed blockchain will become part of the financial infrastructure of the future. We expected individual users to lead, but institutions moved faster.”
For Fish, the next stage involves a broader range of assets and financial clients.
“What gets redefined next is how assets are issued, traded, and settled. As traditional assets like US equities come on-chain, a much wider range of financial clients will follow.”
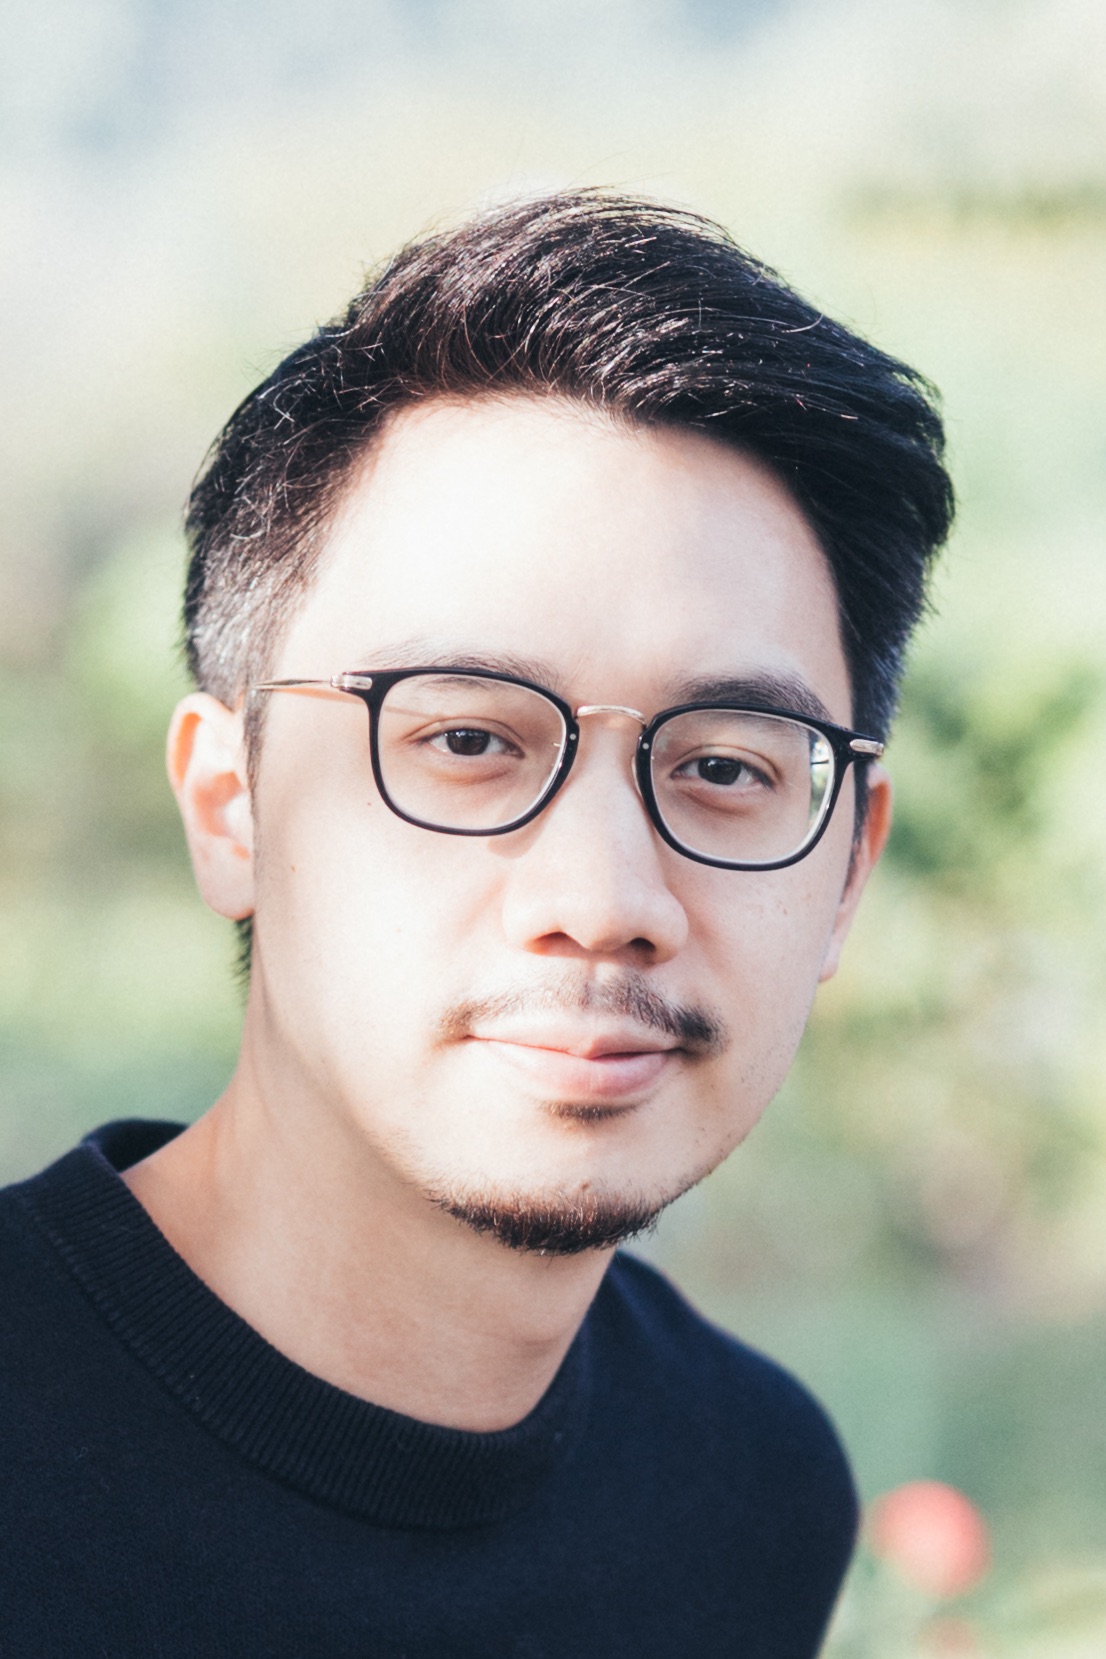
Samuel Tse, Head of Investment and Corporate Finance at Animoca Brands, focuses on investment opportunities across digital assets and agentic AI. He sees digital identity as essential to allowing AI agents to act on behalf of people while keeping transactions within the permissions they set.
He believes users should set clear rules for what an AI agent can do, allowing it to complete transactions without requiring approval for each one.
“Once agents can prove who they represent, hold digital assets, and move value under clear rules, the economy stops being click-by-click. You set the policy once—who, how much, for what—and the agent transacts inside it.”
He describes applications ranging from everyday payments and transfers to subscriptions, swaps and earning returns on idle funds. “That’s agentic transactions: payments, transfers, subscriptions, swaps, even chasing a better rate on idle cash. Identity is the trust layer. Assets and credentials are the spending authority—always accountable to the human who granted permission.”
In Tse’s account, the human remains the source of that authority. The agent acts within the permissions granted to it.
To illustrate how AI agents, digital identity and digital assets might work together, Tse offers a hypothetical Hong Kong parent's weekday.
“A Hong Kong parent’s weekday: top up the child’s Octopus, book a weekend football slot, translate a school notice for the helper, check weather before pickup, restock milk at the member price, and keep leftover budget earning until tomorrow.”
At present, he says, completing these tasks requires navigating services that often operate separately.
“Today that means many apps that don't talk to each other, and rails that struggle with micro payments.”
His proposed alternative brings the tasks together under instructions established by the user.
“With an agent, they set the rules once and let it decide what to do. Identity unlocks trust and member prices without oversharing. Digital assets fit the money—per-use fees, hard limits, yield until spend.”
For Tse, this combination could create opportunities across payments, merchants, identity providers and digital-asset platforms. He compares the potential scale of agentic commerce to an earlier change in how consumers accessed services.
“The iPhone in 2007 rewired how people buy and use services for 20 years. We are just at the beginning of a similar paradigm shift, with outcomes we can barely imagine.”
Discus Fish and Samuel Tse offer two perspectives on the emerging agentic economy, from the blockchain infrastructure enabling transactions to the digital identity and permissions that allow AI agents to act on people's behalf. At CVCF 2026, these ideas will become part of a wider conversation with the leaders building and investing in this evolving space.
Be part of the conversation. Join industry leaders, founders and investors at CVCF 2026 on 4–5 November and explore the technologies and opportunities shaping the next phase of business.
Exclusive for Ventureport readers: Use code cvcf26vp to access a Full Access Pass for HK$300, subject to confirmation by the organiser.
Keep Reading
Brains, bots and the future: Who’s really in control?
Updated
January 8, 2026 6:32 PM
Adoration and disdain, the polarised reactions for generative AI. ILLUSTRATION: YORKE YU
When British-Canadian cognitive psychologist and computer scientist Geoffrey Hinton joked that his ex-girlfriend once used ChatGPT to help her break up with him, he wasn’t exaggerating. The father of deep learning was pointing to something stranger: how machines built to mimic language have begun to mimic thought — and how even their creators no longer agree on what that means.
In that one quip — part humor, part unease — Hinton captured the paradox at the center of the world’s most important scientific divide. Artificial intelligence has moved beyond code and circuits into the realm of psychology, economics and even philosophy. Yet among those who know it best, the question has turned unexpectedly existential: what, if anything, do large language models truly understand?
Across the world’s AI labs, that question has split the community into two camps — believers and skeptics, prophets and heretics. One side sees systems like ChatGPT, Claude, and Gemini as the dawn of a new cognitive age. The other insists they’re clever parrots with no grasp of meaning, destined to plateau as soon as the data runs out. Between them stands a trillion-dollar industry built on both conviction and uncertainty.
Hinton, who spent a decade at Google refining the very neural networks that now power generative AI, has lately sounded like a man haunted by his own invention. Speaking to Scott Pelley on the CBS 60 Minutes interview aired October 8, 2023, Hinton said, “I think we're moving into a period when for the first time ever we may have things more intelligent than us.” . He said it not with triumph, but with visible worry.
Yoshua Bengio, his longtime collaborator, sees it differently. Speaking at the All In conference in Montreal, he told TIME that future AI systems "will have stronger and stronger reasoning abilities, more and more knowledge," while cautioning about ensuring they "act according to our norms". And then there’s Gary Marcus, the cognitive scientist and enduring critic, who dismisses the hype outright: “These systems don’t understand the world. They just predict the next word.”
It’s a rare moment in science when three pioneers of the same field disagree so completely — not about ethics or funding, but about the very nature of progress. And yet that disagreement now shapes how the future of AI will unfold.
In the span of just two years, large language models have gone from research curiosities to corporate cornerstones. Banks use them to summarize reports. Lawyers draft contracts with them. Pharmaceutical firms explore protein structures through them. Silicon Valley is betting that scaling these models — training them on ever-larger datasets with ever-denser computers — will eventually yield something approaching reasoning, maybe even intelligence.
It’s the “bigger is smarter” philosophy, and it has worked — so far. OpenAI’s GPT-4, Anthropic’s Claude, and Google’s Gemini have grown exponentially in capability . They can write code, explain math, outline business plans, even simulate empathy. For most users, the line between prediction and understanding has already blurred beyond meaning. Kelvin So, who is now conducting AI research in PolyU SPEED, commented , “AI scientists today are inclined to believe we have learnt a bitter lesson in the advancement from the traditional AI to the current LLM paradigm. That said, scaling law, instead of human-crafted complicated rules, is the ultimate law governing AI.”
But inside the labs, cracks are showing. Scaling models have become staggeringly expensive, and the returns are diminishing. A growing number of researchers suspect that raw scale alone cannot unlock true comprehension — that these systems are learning syntax, not semantics; imitation, not insight.
That belief fuels a quiet counter-revolution. Instead of simply piling on data and GPUs, some researchers are pursuing hybrid intelligence — systems that combine statistical learning with symbolic reasoning, causal inference, or embodied interaction with the physical world. The idea is that intelligence requires grounding — an understanding of cause, consequence, and context that no amount of text prediction can supply.
Yet the results speak for themselves. In practice, language models are already transforming industries faster than regulation can keep up. Marketing departments run on them. Customer support, logistics and finance teams depend on them. Even scientists now use them to generate hypotheses, debug code and summarize literature. For every cautionary voice, there are a dozen entrepreneurs who see this technology as a force reshaping every industry. That gap — between what these models actually are and what we hope they might become — defines this moment. It’s a time of awe and unease, where progress races ahead even as understanding lags behind.
Part of the confusion stems from how these systems work. A large language model doesn’t store facts like a database. It predicts what word is most likely to come next in a sequence, based on patterns in vast amounts of text. Behind this seemingly simple prediction mechanism lies a sophisticated architecture. The tokenizer is one of the key innovations behind modern language models. It takes text and chops it into smaller, manageable pieces the AI can understand. These pieces are then turned into numbers, giving the model a way to “read” human language. By doing this, the system can spot context and relationships between words — the building blocks of comprehension.
Inside the model, mechanisms such as multi-head attention enable the system to examine many aspects of information simultaneously, much as a human reader might track several storylines at once.
Reinforcement learning, pioneered by Richard Sutton, a professor of computing science at the University of Alberta, and Andrew Barto, Professor Emeritus at the University of Massachusetts, mimics human trial-and-error learning. The AI develops “value functions” that predict the long-term rewards of its actions. Together, these technologies enable machines to recognize patterns, make predictions and generate text that feels strikingly human — yet beneath this technical progress lies the very divide that cuts to the heart of how intelligence itself is defined.
This placement works well because it elaborates on the technical foundations after the article introduces the basic concept of how language models work, and before it transitions to discussing the emergent behaviors and the “black box problem.”
Yet at scale, that simple process begins to yield emergent behavior — reasoning, problem-solving, even flashes of creativity that surprise their creators. The result is something that looks, sounds and increasingly acts intelligent — even if no one can explain exactly why.
That opacity worries not just philosophers, but engineers. The “black box problem” — our inability to interpret how neural networks make decisions — has turned into a scientific and safety concern. If we can’t explain a model’s reasoning, can we trust it in critical systems like healthcare or defense?
Companies like Anthropic are trying to address that with “constitutional AI,” embedding human-written principles into model training to guide behavior. Others, like OpenAI, are experimenting with internal oversight teams and adversarial testing to catch dangerous or misleading outputs. But no approach yet offers real transparency. We’re effectively steering a ship whose navigation system we don’t fully understand. “We need governance frameworks that evolve as quickly as AI itself,” says Felix Cheung, Founding Chairman of RegTech Association of Hong Kong (RTAHK). “Technical safeguards alone aren't enough — transparent monitoring and clear accountability must become industry standards.”
Meanwhile, the commercial race is accelerating. Venture capital is flowing into AI startups at record speed. OpenAI’s valuation reportedly exceeds US$150 billion; Anthropic, backed by Amazon and Google, isn’t far behind. The bet is simple: that generative AI will become as indispensable to modern life as the internet itself.
And yet, not everyone is buying into that vision. The open-source movement — championed by players like Meta’s Llama, Mistral in France, and a fast-growing constellation of independent labs — argues that democratizing access is the only way to ensure both innovation and accountability. If powerful AI remains locked behind corporate walls, they warn, progress will narrow to the priorities of a few firms.
But openness cuts both ways. Publicly available models are harder to police, and their misuse — from disinformation to deepfakes — grows as easily as innovation does. Regulators are scrambling to balance risk and reward. The European Union’s AI Act is the world’s most comprehensive attempt at governance, but even it struggles to define where to draw the line between creativity and control.
This isn’t just a scientific argument anymore. It’s a geopolitical one. The United States, China, and Europe are each pursuing distinct AI strategies: Washington betting on private-sector dominance, Beijing on state-led scaling, Brussels on regulation and ethics. Behind the headlines, compute power is becoming a form of soft power. Whoever controls access to the chips, data, and infrastructure that fuel AI will control much of the digital economy.
That reality is forcing some uncomfortable math. Training frontier models already consumes energy on the scale of small nations. Data centers now rise next to hydroelectric dams and nuclear plants. Efficiency — once a technical concern — has become an economic and environmental one. As demand grows, so does the incentive to build smaller, smarter, more efficient systems. The industry’s next leap may not come from scale at all, but from constraint.
For all the noise, one truth keeps resurfacing: large language models are tools, not oracles. Their intelligence — if we can call it that — is borrowed from ours. They are trained on human text, human logic, human error. Every time a model surprises us with insight, it is, in a sense, holding up a mirror to collective intelligence.
That’s what makes this schism so fascinating. It’s not really about machines. It’s about what we believe intelligence is — pattern or principle, simulation or soul. For believers like Bengio, intelligence may simply be prediction done right. For critics like Marcus, that’s a category mistake: true understanding requires grounding in the real world, something no model trained on text can ever achieve.
The public, meanwhile, is less interested in metaphysics. To most users, these systems work — and that’s enough. They write emails, plan trips, debug spreadsheets, summarize meetings. Whether they “understand” or not feels academic. But for the scientists, that distinction remains critical, because it determines where AI might ultimately lead.
Even inside the companies building them, that tension shows OpenAI’s Sam Altman has hinted that scaling can’t continue forever. At some point, new architectures — possibly combining logic, memory, or embodied data — will be needed. DeepMind’s Demis Hassabis says something similar: intelligence, he argues, will come not just from prediction, but from interaction with the world.
It’s possible both are right. The future of AI may belong to hybrid systems — part statistical, part symbolic — that can reason across multiple modes of information: text, image, sound, action. The line between model and agent is already blurring, as LLMs gain the ability to browse the web, run code, and call external tools. The next generation won’t just answer questions; it will perform tasks.
For startups, the opportunity — and the risk — lies in that transition. The most valuable companies in this new era may not be those that build the biggest models, but those that build useful ones: specialized systems tuned for medicine, law, logistics, or finance, where reliability matters more than raw capability. The winners will understand that scale is a means, not an end.
And for society, the challenge is to decide what kind of intelligence we want to live with. If we treat these models as collaborators — imperfect, explainable, constrained — they could amplify human potential on a scale unseen since the printing press. If we chase the illusion of autonomy, they could just as easily entrench bias, confusion, and dependency.
The debate over large language models will not end in a lab. It will play out in courts, classrooms, boardrooms, and living rooms — anywhere humans and machines learn to share the same cognitive space. Whether we call that cooperation or competition will depend on how we design, deploy, and, ultimately, define these tools.
Perhaps Hinton’s offhand remark about being psychoanalyzed by his own creation wasn’t just a joke. It was an omen. AI is no longer something we use; it’s something we’re reflected in. Every model trained on our words becomes a record of who we are — our reasoning, our prejudices, our brilliance, our contradictions. The schism among scientists mirrors the one within ourselves: fascination colliding with fear, ambition tempered by doubt.
In the end, the question isn’t whether LLMs are the future. It’s whether we are ready for a future built in their image.